TL;DR: For a 5 MB upload over a path with a 31 ms RTT, cold TCP delivered the payload in 325 ms. Two knobs brought it to 72 ms. We introduce and visualize the TCP concepts in play, and explain how warm TCP helps and why it’s not always wise.
TCP was invented in 1974. Since then, it’s been by far the most used protocol for reliable, ordered communication over the internet. It is the technology beneath HTTP/1, HTTP/2, SSH, SMTP and WebSockets, to name only a few. Over the decades of its prevalence, it has been meticulously optimized to deliver data reliably over the messy web that is the public internet. However, for heavy, bursty inference payloads (media input, tight latency budgets) TCP can become a latency bottleneck.
In this post, we show how we reduced network latency for a 5 MB upload from 325 ms to 72 ms.
Using an interactive visual simulation, I hope you’ll see and intuit why TCP can be so slow and how you can make it as fast as the network allows, followed by some important caveats to keep in mind.
The basics
In TCP, a sender and a receiver create a connection, which allows the sender to send a payload to the receiver over network infrastructure. During data transfer, the payload is broken up into packets. Each packet travels through the network, making hops at different routers along the way. Each router receives data from a link into a buffer, then forwards it to another link. When the packet arrives, the receiver sends out an acknowledgment or ack to the sender. The time it takes for one packet to be received and its ack to come back is round trip time RTT. TCP achieves lossless ordered payload at reception by resending unacknowledged packets until full payload is acknowledged from the receiver or the connection is closed.
Below is a simulation based on a real measured request:
The simulation sends a 5 MB payload over a network with a 31 ms RTT. Despite the 31 ms round trip, the payload takes up to 350 ms to arrive, and the network looks largely underutilized.
Reuse connections
The first thing we see is the initial 3-way handshake SYN→SYN-ACK→ACK. This serves to establish the connection between the sender and receiver. Can we do without it?
Yes. We can open a connection once (on startup or first request) and keep it open, so we do not spend 1 RTT on the handshake each time. Both the real measurement and the simulation show the expected improvement, cutting network latency to 295 ms.
Gotchas
- Both the sender and receiver discard connections after some timeout window. Either raise it on the receiver if you own it, ask for longer timeouts, or watch for dead connections and replace them.
- One connection carries one in-flight request at a time, so if you need to handle 20 concurrent requests, pre-warm 20 TCP connections.
In the simulation above, the number of packets in flight (aka the congestion window, cwnd) starts small and grows with every batch. This behavior is controlled by something called a congestion-control algorithm CCA.
Simply put: if you send too many packets under bad network conditions, you clog the router buffers, causing latency to rise further and requests to time out. Send too few packets each time and you will under-utilize the link, increasing latency. CCAs solve this by adapting to network conditions as they detect them.
In this case, CUBIC (the most widely deployed CCA) initializes cwnd to a measly 10 packets carrying 0.0146 MB of data. After that, CUBIC doubles cwnd with each healthy RTT (no packets dropped). If a packet drops, there is congestion somewhere in the path, so CUBIC backs off: it cuts cwnd to 70% of its value and stops growing exponentially for a while.
In our setup at Overshoot, we control both sender and receiver and run over a provisioned high-capacity path, so we raise the initial cwnd from 10 to 3,500 packets, which cuts our upload latency from 295 ms to 72 ms.
The three measurements behind the simulations above: the handshake saved by reusing the connection, then the slow-start rounds saved by a larger initial congestion window.
Gotchas
- cwnd alone is not enough. The receiver has a receive window rwnd, and the sender can have at most min(cwnd, rwnd) packets in flight. I will cover rwnd in a later post.
- When sending N concurrent requests, all with an aggressive initial cwnd, we can have N× more packets in flight than the path can handle. It is better to set the initial cwnd to the maximum safe cwnd divided by N.
Why like this, TCP?
When working with TCP, you will find yourself fighting an uphill battle to ensure reliable low latency. This is the result of a sane design philosophy for a protocol designed to run always everywhere all at once.
Before we move to the philosophy, let’s look at a typical path of a request from a browser to a backend server:
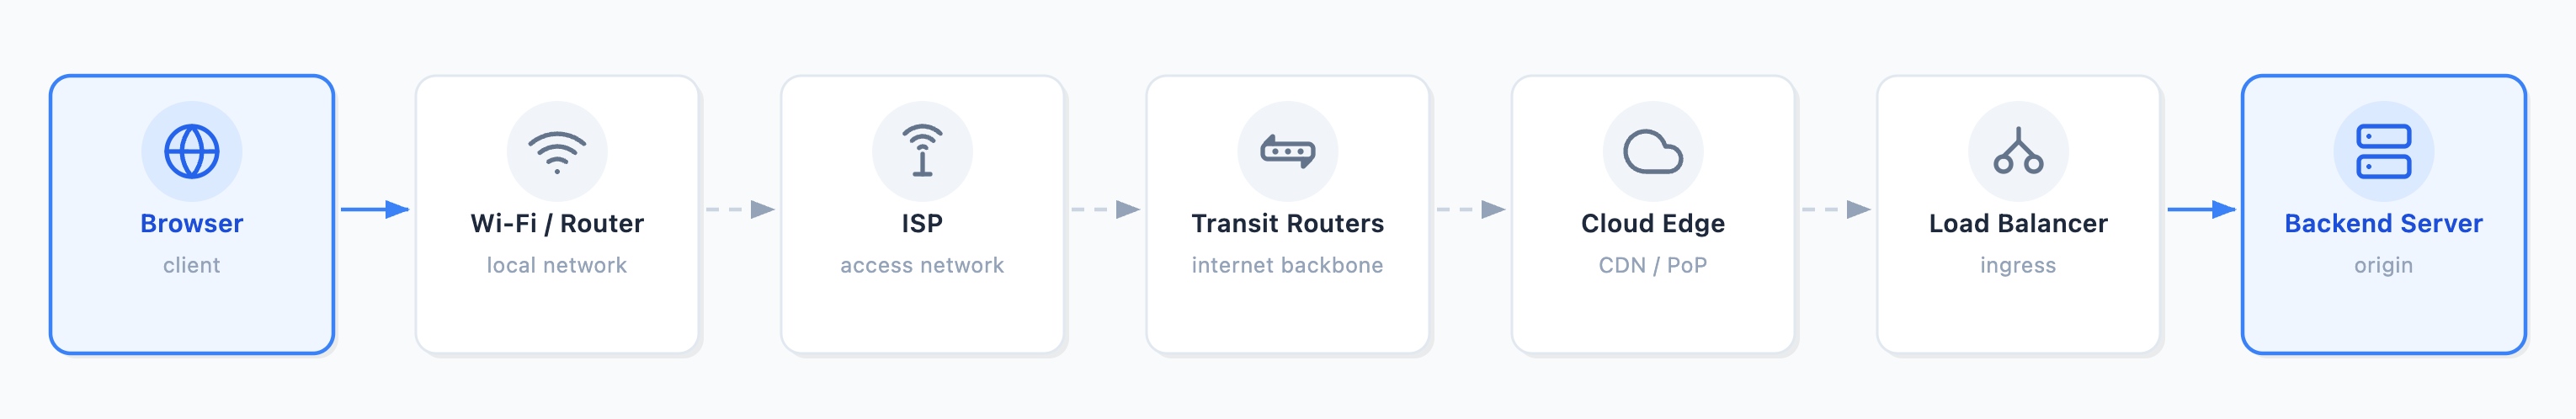
TCP is blind
The internet is a multi-actor space, where honesty and compliance are not guaranteed (shocker, I know). Therefore, we cannot simply ask all the routers in a path to publish their congestion level and plan accordingly. We have to rely on signals like packets that have not been acknowledged past some time window. For our case, this means we cannot anticipate congestion and redirect traffic to avoid tail network latencies. We learn about congestion as it happens.
TCP is defensive
Routers dropping packets can create a vicious cycle as all senders have to send the next batch AND retransmit all dropped packets from the previous batch. If senders keep sending aggressively during congestion, more packets are dropped, additional senders join before the old ones are finished, and the congestion grows much like a traffic jam. For this reason, congestion-control algorithms back off defensively. A short-lived burst overwhelming an ISP router causes all the senders going through that router to back off and enter a slow recovery cycle.
TCP is polite
Given the fragility and shared congestion effect across router users, one overly aggressive actor might be able to improve their own performance while hurting others’. It is bad networking etiquette to start with overly large cwnd, or to recover from a congestion signal too quickly. TCP is designed with polite defaults that are needed when routers are both shared and congestion-prone.
For media inference and other large, latency-sensitive payloads over the internet, the answer is to own as much of the path as you can. Own the sender and receiver, then move as much of the path as you can out of the public internet. Own your network, or at least ride your cloud provider’s premium network to your GPU. With ownership over routers, the network becomes a resource you partition among your payloads. Short of owning the network, keep your connections as warm as possible, provision for concurrency, and be as aggressive as your path quality justifies.